Claude Sonnet 5.5: Features, Pricing and Benchmarks
Claude Sonnet 5.5 is not Anthropic’s most powerful model. That may be exactly why it matters.
Released on September 28, 2026, Sonnet 5.5 targets everyday work: fixing bugs, reviewing code, analyzing documents, building slides, cleaning spreadsheets, and completing well-scoped agent tasks. Opus 5.5 remains the stronger option for difficult, open-ended judgment.
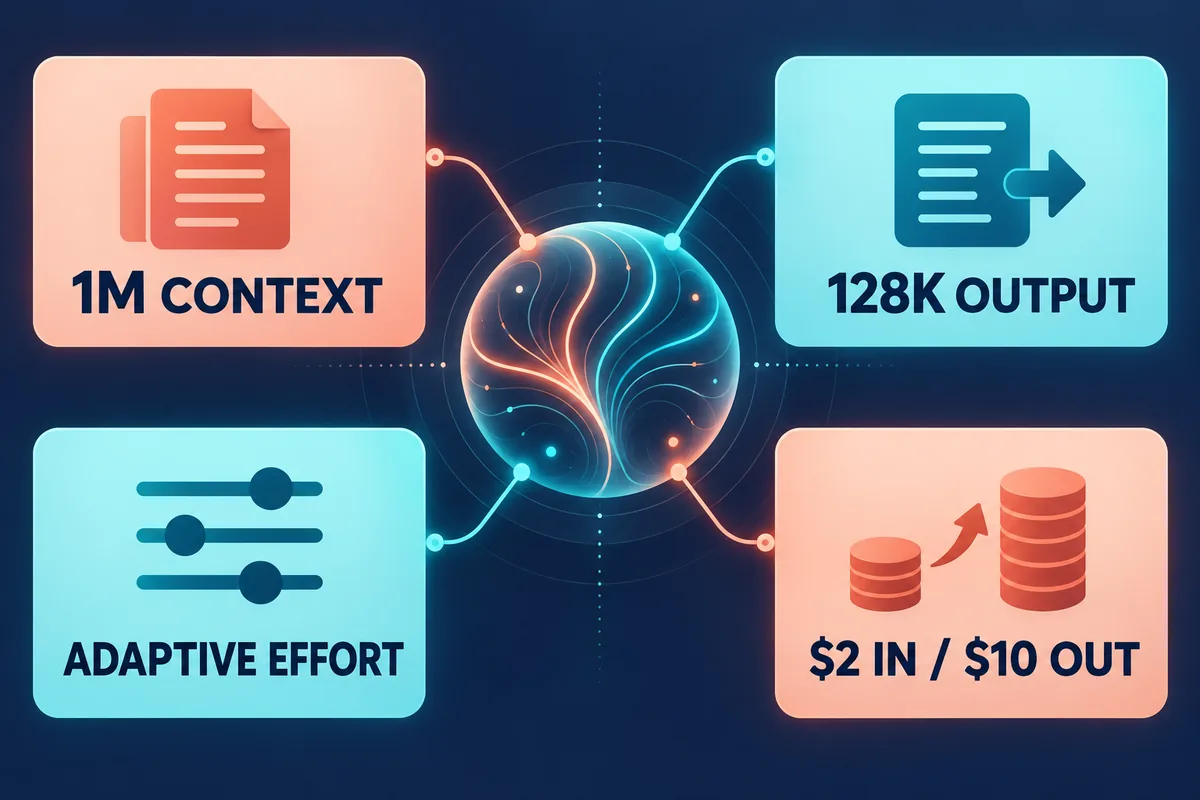
The result is a model that looks less like a showcase and more like a production workhorse. It has a one-million-token context window, adaptive thinking, image input, and a 128,000-token output limit. The API price remains $2 per million input tokens and $10 per million output tokens.
Those specifications are impressive. The benchmark headlines need context, though. This guide separates documented features, Anthropic’s claims, and early outside testing so you can decide where Claude Sonnet 5.5 actually fits.
What is Claude Sonnet 5.5?
Claude Sonnet 5.5 is Anthropic’s fast, general-purpose model for coding, agents, visual work, and professional tasks. It is the second release in the Claude 5.5 family after Opus 5.5. Anthropic says Sonnet is best for work with a clear goal, while Opus remains stronger when a task needs sustained judgment across unclear or changing requirements.
Anyone can use Sonnet 5.5 through Claude on the web, iOS, or Android. Developers can call claude-sonnet-5-5 through the Claude API or use Amazon Bedrock, Google Cloud, Microsoft Foundry, and Claude Platform on AWS.
According to the official model documentation, Sonnet 5.5 accepts text and images and returns text. Its reliable knowledge cutoff and training-data cutoff are June 2026. Anthropic promises model availability until at least September 28, 2027.
Claude Sonnet 5.5 specifications
| Specification | Claude Sonnet 5.5 |
|---|---|
| Context window | 1 million tokens |
| Maximum output | 128,000 tokens |
| Batch output beta | Up to 300,000 tokens |
| Input price | $2 per million tokens |
| Output price | $10 per million tokens |
| Cache read price | $0.20 per million tokens |
| Five-minute cache write | $2.50 per million tokens |
| One-hour cache write | $4 per million tokens |
| Batch API discount | 50% on input and output |
| Thinking | Adaptive |
Pricing can change, so check Anthropic’s current page before estimating a production budget.
What changed from Claude Sonnet 5?
Anthropic reports that Sonnet 5.5 generates output more than 30% faster than Sonnet 5. It keeps the same token price but often uses fewer tokens to finish a task. In the company’s testing, that reduced the total cost of typical work by up to 30%.
The larger change is how the model works through tasks. Early customers reported fewer tool calls, fewer failed actions, and less unnecessary web searching. Slack said its offline tests used about 14% fewer output tokens. Zendesk reported that support tickets were processed 20% faster. These are customer results highlighted by Anthropic, not neutral guarantees for every workload.
The model also writes more directly and shows stronger visual judgment. Anthropic highlights user interfaces, diagrams, slides, and spreadsheets as intended uses, although every important draft still needs review.
Adaptive effort changes the cost equation
Sonnet 5.5 uses adaptive thinking. Developers can choose low, medium, high, xhigh, or max effort depending on the task. Lower effort reduces time and token use. Higher effort lets the model reason longer and check more of its work.
Claude apps and Claude Code use Medium by default. The Claude Platform API defaults to High. That difference matters when people compare cost or quality. Two tests using the same model can produce very different results if their effort settings do not match.
This is also why the phrase “half the price of Opus” can mislead. Sonnet’s token rates are half of Opus 5.5, but a high-effort Sonnet run may generate more tokens or take more steps. Compare total cost per successful task, not only the price printed beside the model name.
Claude Sonnet 5.5 benchmarks: strong, with caveats
Anthropic reports a large coding gain. Sonnet 5.5 scored 70.6% on Terminal-Bench 4.0, compared with 10.3% for Sonnet 5 and 66.4% for Opus 5.5 at its reported setting. On CursorBench 4.0, Sonnet 5.5 reached 55.5%, close to Opus 5.5 at 57.8%. It also scored almost level with Opus on GDPval-AA, which tests professional work across many occupations.
Benchmarks are useful, but each measures a narrow setup. Anthropic notes that Max effort scored below Xhigh on one coding test because extra review steps caused timeouts or out-of-scope edits. More thinking did not always produce a better score.
An early independent coding comparison by Bito used six real development tasks. Sonnet 5.5 won each task, scored 38.5 versus 33.3, cost $0.78 rather than $2.65 per session, and finished in 3.8 minutes rather than 10.7. However, Bito compared Sonnet 5.5 at its Medium default with Sonnet 5 at High. It is valuable workflow evidence, not a clean same-effort laboratory test.
Sonnet 5.5 vs Opus 5.5
Choose Sonnet 5.5 for:
- focused bug fixes and feature work;
- high-volume reviews, support, and document workflows;
- fast iterations on interfaces, slides, and spreadsheets;
- agents with clear tools, limits, and success criteria;
- workloads where latency and repeated cost matter.
Choose Opus 5.5 for:
- open-ended planning with unclear requirements;
- architecture or strategy that needs sustained judgment;
- complex investigations where the model must revise its approach;
- difficult work where quality matters more than speed.
A practical pattern is to let Opus design the approach and Sonnet perform the defined work. Yet routing should follow your own evaluation. A polished answer is not proof that the underlying decision was correct.
Coding, documents, design, and agent work
For developers, the main appeal is speed across a full coding loop. Sonnet can inspect files, plan a contained change, edit code, run tests, and review the result. The model performs best when the request defines the outcome and asks for real verification before completion.
For knowledge workers, one model can analyze sources, build a spreadsheet, create a diagram, and shape findings into a deck. Its large context window helps, but does not replace source boundaries or fact checks.
For agents, give Sonnet a small toolset and an explicit stopping rule. Track success rate, retries, tool-call count, latency, and human corrections. These measures reveal more than a public leaderboard.
Migration and safety details developers should not miss
Moving from Sonnet 5 is not only a model-name change. Anthropic documents several breaking differences. Up-front thinking is now controlled with between_tools. Forced tool use returns an error. Thinking blocks belong to the model and conversation. Some older computer-use tool versions are no longer accepted. Text between tool calls may also arrive inside thinking blocks, which can affect streaming interfaces.
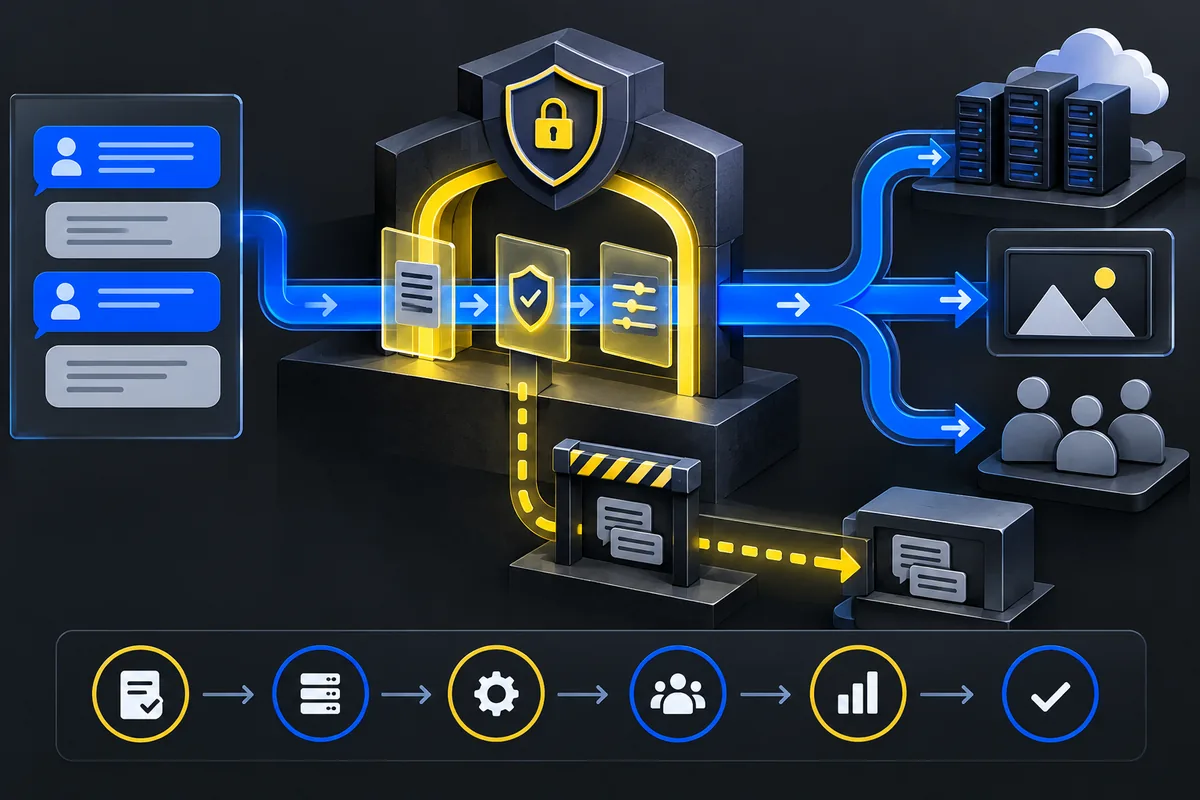
Sonnet 5.5 is also the first Sonnet release with cyber safeguards similar to Anthropic’s most capable models. Higher-risk cyber requests may fall back to Sonnet 5. Biology protections remain aligned with Sonnet 5. Routine development and most life-science work should be unaffected, although false positives can occur.
Before switching production traffic, replay a private evaluation set. Test accuracy, total cost, latency, safety fallbacks, structured output, tool behavior, and failure recovery. Then roll out gradually and monitor real tasks.
Watch the official Claude Sonnet 5.5 introduction
Video description: Anthropic’s official launch video introduces Sonnet 5.5 as a faster, clearer model for everyday coding and professional work. Treat performance statements as vendor claims and compare them with your own tests.
Video caption: Anthropic’s short official overview of where Sonnet 5.5 fits in the Claude model family.
Claude Sonnet 5.5 launch posts on X
Claude introduced Sonnet 5.5 as a clear Sonnet 5 upgrade that runs more than 30% faster and can cost less per completed task.
View the official Claude launch post on X
Claude’s official launch post summarizes the model’s speed, cost, and everyday-work positioning.
Anthropic developer Lydia Hallie confirmed that Sonnet 5.5 was available in Claude Code on launch day.
View the Claude Code availability post on X
A launch-day developer post confirming Sonnet 5.5 availability in Claude Code.
Final verdict
Claude Sonnet 5.5 is compelling because it improves the middle of the market. It brings near-flagship results to many focused tasks while remaining faster and cheaper to run than Opus at comparable settings. Coding is the headline gain, but documents, data, design, and agent work make the model broadly useful.
The best setting is not always Max, and the cheapest token price is not always the lowest task cost. Start at Medium for routine work, move higher only when your evaluation shows a real gain, and reserve Opus for problems that need deeper judgment. Sonnet 5.5 should earn its place through completed, verified work—not benchmark excitement alone.
Frequently asked questions
When was Claude Sonnet 5.5 released?
Anthropic released Claude Sonnet 5.5 on September 28, 2026.
How much does Claude Sonnet 5.5 cost?
The standard Claude API price is $2 per million input tokens and $10 per million output tokens. Caching and batch processing can reduce certain costs.
What is the Claude Sonnet 5.5 context window?
It supports a one-million-token context window and up to 128,000 output tokens in standard requests.
Is Claude Sonnet 5.5 better than Opus 5.5?
Not for every task. Sonnet is faster and cheaper for focused work. Anthropic says Opus remains stronger for complex, open-ended tasks that require sustained judgment.
Can I use Claude Sonnet 5.5 in Claude Code?
Yes. Current Claude Code versions can resolve the sonnet alias to Sonnet 5.5, and developers can select the model directly where supported.
Sources and editorial notes
- Anthropic: Introducing Claude Sonnet 5.5
- Claude Platform: Sonnet 5.5 model documentation
- Anthropic: Claude Sonnet 5.5 System Card
- Claude developer blog: Building with Claude Sonnet 5.5
- Bito: Claude Sonnet 5.5 vs Sonnet 5
Editorial note: This article distinguishes Anthropic’s claims, customer testimonials featured by Anthropic, and third-party testing. Prices, availability, safeguards, and model behavior can change. Verify production decisions against current documentation and your own evaluation set.
Building 120+ free AI-powered SEO tools — every article is written and tested with them. About us
Try the tools we used
All articles are written with SEO Fragments. Sign in free and use the same tools.
Get started free →Read next
- Claude Haiku 5.5: The Small Model That Wants to Do the Busy WorkClaude Haiku 5.5 is Anthropic's fastest and lowest-cost small model yet. See its pricing, benchmarks, limits, safety controls, and best use cases.
- Gemini 4 Argon Explained: Access, Price and BenchmarksGemini 4 Argon promises long-running AI workflows, strong coding and a 1M-token output limit. Here is what Google announced—and what remains unknown.
- AI Visibility Audit: A Practical 5-Step GuideAn AI tool can recommend your competitor while ignoring your brand. It can also name you without linking to your site. Both results affect visibility, but they…